English technical overview. The complete supplied article is available in Persian using the language switch.
Overview
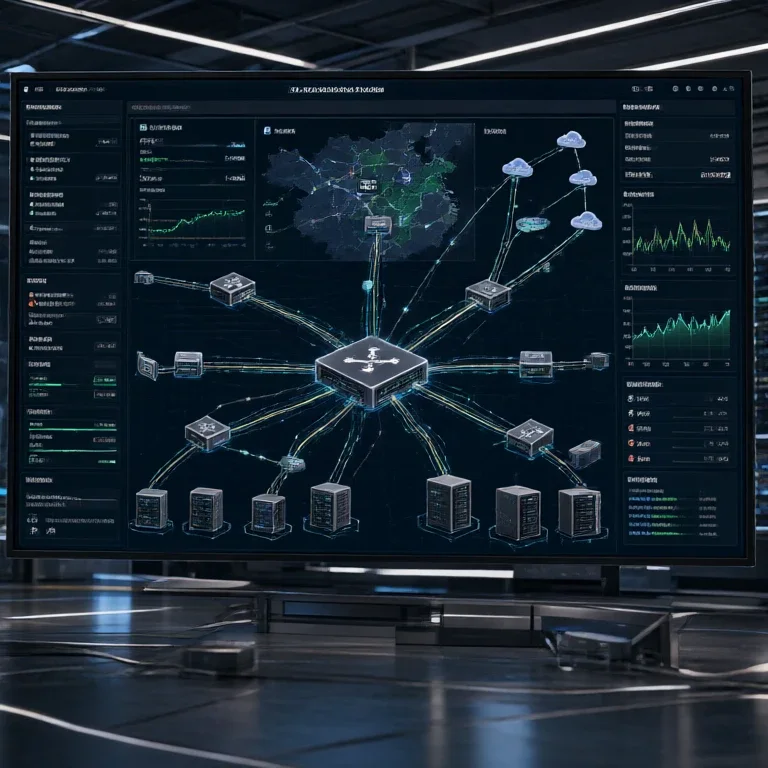
Combine metrics, logs and operational context to understand service health.
Design considerations
Monitoring checks known conditions; observability helps investigate why a system behaves as it does. Collect useful metrics, logs and events with reliable timestamps. Define service priorities and a baseline before setting alerts.
Operational practice
Alert on actionable symptoms and assign ownership. Track capacity and recurring incidents. Keep dashboards readable, protect operational data and rehearse response and recovery procedures.